LocalAI MCP Server
 by mudler
LocalAI is the open-source AI engine. Run any model - LLMs, vision, voice, image, video - on any hardware. No GPU required.
LocalAI is an open-source mcp server by mudler, written mainly in Go, with 50,108 GitHub stars and the MIT license. Its code was last updated Nov 1, 2026.
LocalAI is your own AI, on your own hardware, ready to work for you. It is open source. Chat with open models, run agents that use your files, and work on documents with your team. It also does voice, images, video and more. No GPU required.
- Agents, documents and a team: chats and saved agents that use tools, MCP servers, files, collections and skills. Users, roles, quotas and shared folders for a team (development builds).
- Add-ons: an admin installs add-ons from a library: Office, Sandbox, Tables, chat apps (Telegram, Slack, Discord), mail, calendar and more (development builds).
- Every kind of model, one API: text, vision, voice, images, video and embeddings, in the OpenAI, Anthropic and ElevenLabs formats, with more than 80 backends. Each backend is its own image, pulled only when a model needs it.
- Your hardware: NVIDIA, AMD, Intel, Apple Silicon, Vulkan, NVIDIA Jetson or CPU only. The server, the models and your files stay on your own machines.
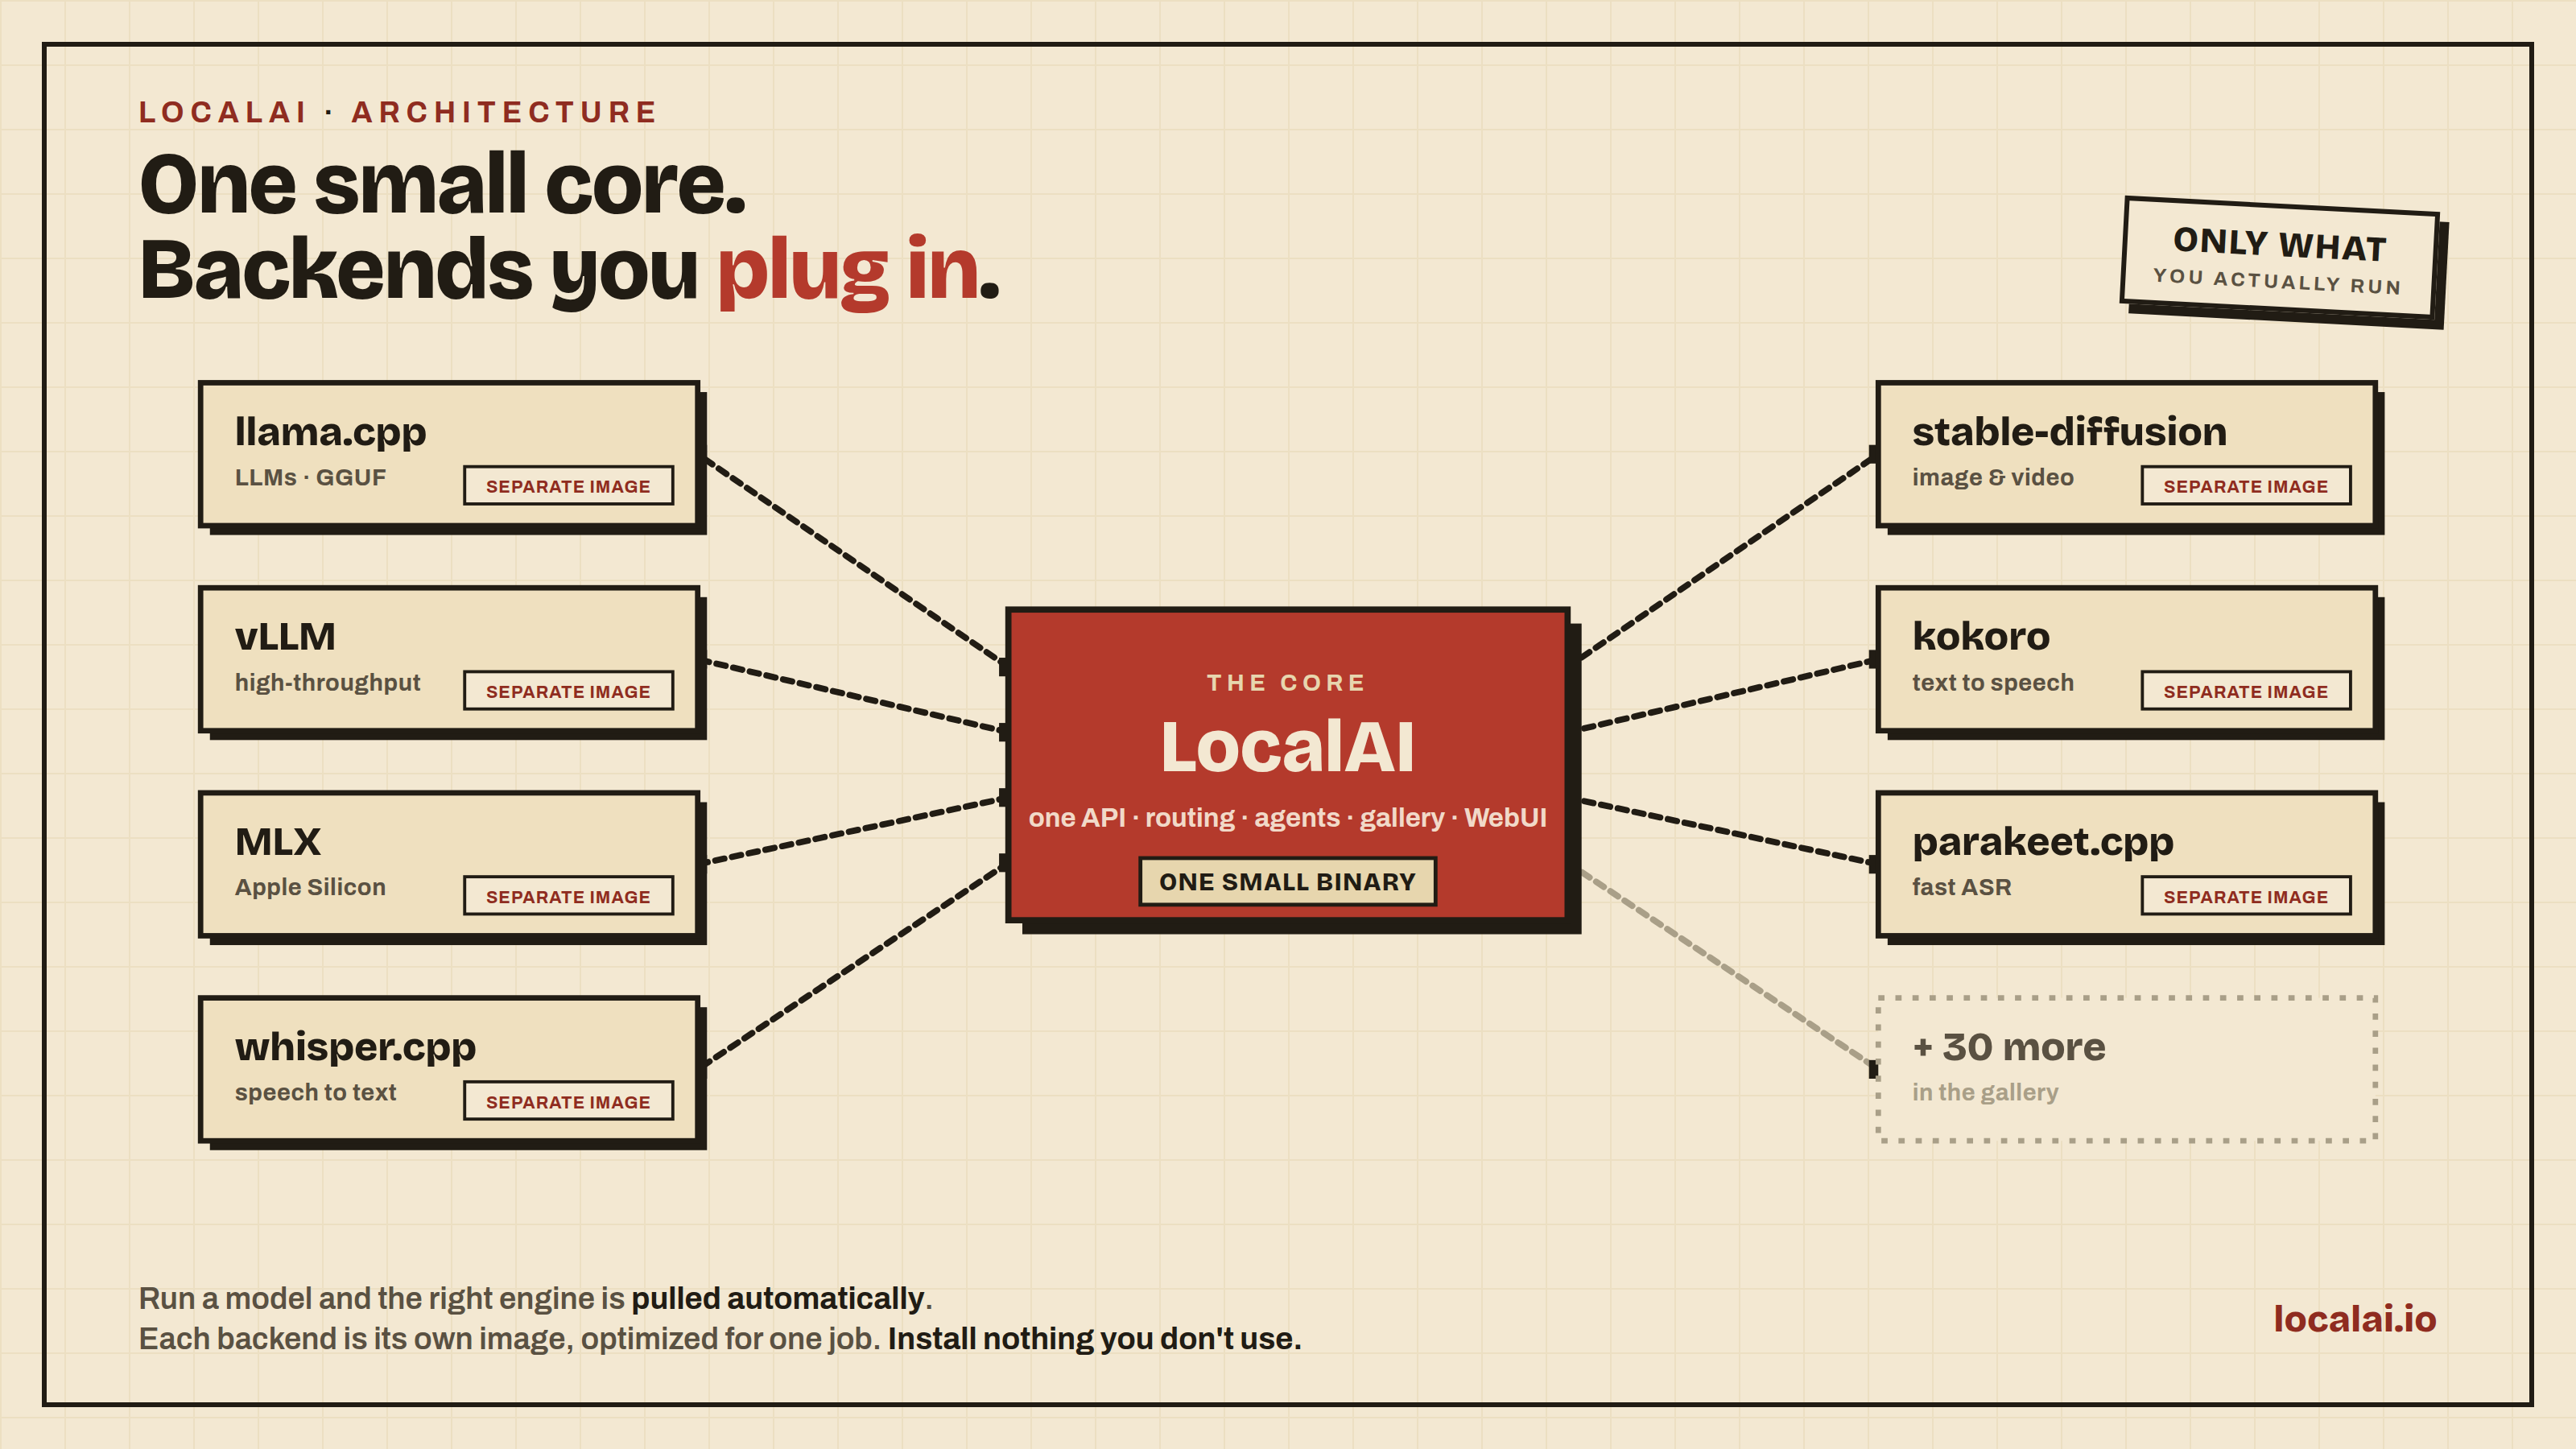
Created by Ettore Di Giacinto and maintained by the LocalAI team.
Quick start
Script (Linux, and macOS on Apple Silicon): it downloads the release binary for your machine and checks it against the release checksums.
curl -sSL https://localai.io/install.sh | sh
local-ai run qwen3-4b
Container (Docker, podman, ...):
docker run -ti --name local-ai -p 8080:8080 localai/localai:latest
macOS app: download LocalAI.dmg. The DMG is signed with an Apple Developer ID and notarized.
The script, the app and the latest container image give version 4.12.1. The add-ons, Office, Sandbox and team features described below need a development build or a newer release.
Then open http://localhost:8080. To restart an existing container, use docker start -i local-ai. More ways to install: Install LocalAI.
# NVIDIA, CUDA 13
docker run -ti --name local-ai -p 8080:8080 --gpus all localai/localai:latest-gpu-nvidia-cuda-13

# NVIDIA, CUDA 12
docker run -ti --name local-ai -p 8080:8080 --gpus all localai/localai:latest-gpu-nvidia-cuda-12

# NVIDIA Jetson ARM64 (CUDA 12, for AGX Orin and similar)
docker run -ti --name local-ai -p 8080:8080 --gpus all localai/localai:latest-nvidia-l4t-arm64

# NVIDIA Jetson ARM64 (CUDA 13, for DGX Spark)
docker run -ti --name local-ai -p 8080:8080 --gpus all localai/localai:latest-nvidia-l4t-arm64-cuda-13

# AMD (ROCm)
docker run -ti --name local-ai -p 8080:8080 --device=/dev/kfd --device=/dev/dri --group-add=video localai/localai:latest-gpu-hipblas

# Intel (oneAPI)
docker run -ti --name local-ai -p 8080:8080 --device=/dev/dri/card1 --device=/dev/dri/renderD128 localai/localai:latest-gpu-intel

# Vulkan
docker run -ti --name local-ai -p 8080:8080 localai/localai:latest-gpu-vulkan
LocalAI detects your GPU and downloads the matching backend. See GPU Acceleration.
</details>Load a model:
# From the model gallery (list it with `local-ai models list` or at https://models.localai.io)
local-ai run qwen3-4b
# From Hugging Face
local-ai run huggingface://TheBloke/phi-2-GGUF/phi-2.Q8_0.gguf
# From the Ollama OCI registry
local-ai run ollama://gemma:2b
# From a standard OCI registry (for example Docker Hub)
local-ai run oci://localai/phi-2:latest
To talk to a running server from the terminal, start the built-in agent in another shell. It asks you to approve anything that changes state. See the Terminal agent docs.
local-ai chat --model qwen3-4b
More in the Quickstart.
What you can do
| Area | What it gives you |
|---|---|
| Chats | Conversations the server keeps, with saved agents that use tools, MCP, skills and files, triggers, and chat apps |
| Add-ons | Office, Sandbox, Tables, Telegram, Slack, Discord, mail, calendar and more install from a library and run beside the server (development builds) |
| Text generation | llama.cpp, transformers, vllm ... and more, with an OpenAI-compatible tools API and constrained grammars |
| Speech | Text to audio, audio to text, voice activity detection (Silero-VAD) and the Realtime API for speech-to-speech |
| Images and vision | Image generation, the Vision API and object detection |
| Search | Embeddings and a reranker |
| Operations | API key auth, user quotas and roles, distributed mode (PostgreSQL + NATS) and P2P inferencing |
| Models and backends | Models from Hugging Face and a Backend Gallery to install or remove backends on the fly, plus the integrated web UI |
LocalAI has more than 80 backends. Hardware acceleration covers NVIDIA (CUDA 12 and 13), AMD (ROCm), Intel (oneAPI/SYCL), Apple Silicon (Metal), Vulkan and NVIDIA Jetson (L4T). See the Backend and Model Compatibility Table.
Backends we build
Most backends wrap a best-in-class upstream engine. A handful of them are native C/C++/GGML engines (no Python at inference) developed and maintained by the LocalAI project itself:
| Backend | What it does |
|---|---|
| vllm.cpp | From-scratch C++20 port of vLLM for text generation: paged KV cache, continuous batching, prefix caching, safetensors + GGUF loading, engine-enforced structured output, on CPU, CUDA, Metal and Vulkan. Also serves MiniMax-H3 joint video+audio generation |
| parakeet.cpp | C++/GGML port of NVIDIA NeMo Parakeet ASR (tdt/ctc/rnnt/hybrid), with cache-aware streaming transcription |
| moss-transcribe.cpp | C++/GGML port of OpenMOSS MOSS-Transcribe-Diarize: joint long-form transcription, speaker diarization and timestamping in a single pass |
| moss-tts.cpp | C++/GGML port of the OpenMOSS MOSS-TTS family: text-to-speech (MOSS-TTS-Local v1.5, 48 kHz stereo) with reference-audio voice cloning, through the MOSS-Audio-Tokenizer neural codec |
| magpie-tts.cpp | C++/GGML port of NVIDIA's Magpie TTS Multilingual 357M: 22.05 kHz mono text-to-speech in 5 voices and 9+ languages, with the NanoCodec neural codec and tokenizer/G2P embedded in a single GGUF |
| ced.cpp | C++/GGML port of the CED audio-tagging models: sound-event classification (527-class AudioSet) over REST and the realtime API for live recognition |
| voice-detect.cpp | Speaker recognition and voice analysis (ECAPA-TDNN, WeSpeaker, ERes2Net, CAM++, wav2vec2 age/gender/emotion), replacing the Python speaker-recognition backend |
| vibevoice.cpp | Native port of Microsoft VibeVoice for TTS (voice cloning) and long-form ASR with speaker diarization |
| rf-detr.cpp | Native RF-DETR object detection and instance segmentation |
| locate-anything.cpp | Open-vocabulary object detection and visual grounding (LocateAnything-3B) |
| depth-anything.cpp | Depth Anything 3 monocular metric depth + camera pose estimation |
| face-detect.cpp | Face detection, recognition, demographics and anti-spoofing (SCRFD/ArcFace, YuNet/SFace), replacing the Python insightface backend |
| timestral.cpp | Mistral Timestral time-series forecasting: quantile forecasts with covariates, on the CPU |
| trellis2.cpp | C++/GGML port of Microsoft TRELLIS.2: single-image to textured 3D mesh (GLB with PBR materials) |
| gem-x.cpp | Live human motion capture with SOMA and SMPL pose streams (CPU/Vulkan) |
| kimodo.cpp | C++/GGML text-to-motion on CPU and Vulkan, exported as animated skeleton GLB |
| privacy-filter.cpp | Standalone GGML PII/NER token-classification engine powering LocalAI's PII redaction tier |
| LocalVQE | Joint acoustic echo cancellation, noise suppression, and dereverberation |
| local-store | Local-first vector database for embeddings (shipped in-tree) |
We also maintain apex-quant, a per-tensor, per-layer quantization recipe for Mixture-of-Experts models that exploits their structural sparsity to produce GGUFs matching or beating Q8_0 quality - and they run out of the box on stock llama.cpp.
Latest news
<!-- Next release: add its entry here, newest first, when the release post is published: month, one line, and a link to the post. Do not add a date or a link before the post exists. -->-
October 2026: LocalAI 4.12.1 — A security fix for the policy on URLs that users give. Redirect targets are now checked on every hop. Release notes
-
October 2026: LocalAI 4.12.0 — A redesigned web UI, streaming voice answers, decision routing with the
/v1/decisionsAPI, image upscaling in Studio and Qdrant stores. Release notes -
October 2026: LocalAI 4.11.0 — Audio scenes with transcription, speaker labels, and sound detection. Also the Decisions API (
/v1/systemone), model failover chains, signed OCI galleries, and Kimodo text-to-animation. Release notes -
September 2026: LocalAI 4.10.0 — A fleet operations dashboard, one credentials file for private model sources, and
local-ai benchmarkfor measuring model latency and throughput. Release notes -
August 2026: LocalAI 4.9.0 — Deny-by-default authentication, opt-in chat context compression, unified model and backend management, and MiniMax-H3 video generation with audio. Release notes
Older news and the full release notes: GitHub Releases and the blog.
Resources
- Documentation and the Quickstart
- LLM fine-tuning guide, build from source and Kubernetes installation
- Integrations and community projects
- Examples, including the realtime voice assistant demo
- Contributing and security policy
Team
LocalAI is maintained by a small team of humans, together with the wider community of contributors.
- Ettore Di Giacinto — original author and project lead
- Richard Palethorpe — maintainer
A huge thank you to everyone who contributes code, reviews PRs, files issues, and helps users in Discord. See the full contributors list.
Sponsors
Support the project by becoming a backer or sponsor. A huge thank you to our sponsors, who cover CI expenses, and to the individual sponsors listed on GitHub and buymeacoffee. Special shout out to drikster80.
<p align="center"> <a href="https://www.spectrocloud.com/" target="blank"> <img height="120" src="https://github.com/user-attachments/assets/72eab1dd-8b93-4fc0-9ade-84db49f24962"> </a> <a href="https://solstone.app/" target="blank" > <img height="120" src="https://solpbc.org/brands/assets/solstone/png/lockup-solstone-app-512.png"> </a> </p>License
MIT. LocalAI is created by Ettore Di Giacinto and maintained by the LocalAI team. The LocalAI name, logo and mascot art are not covered by the MIT license: all rights reserved. See BRAND-USAGE.md for what you may do with them.
<details> <summary>Citation and acknowledgements</summary>@misc{localai,
author = {Ettore Di Giacinto},
title = {LocalAI: the open source AI engine},
year = {2026},
publisher = {GitHub},
journal = {GitHub repository},
howpublished = {\url{https://github.com/mudler/LocalAI}},
}
LocalAI couldn't have been built without the help of great software already available from the community: llama.cpp, stanford_alpaca, llama-go, alpaca.cpp, Stable-Diffusion-NCNN, whisper.cpp, piper and exo (MLX distributed auto-parallel sharding).
</details> <a href="https://github.com/mudler/LocalAI/graphs/contributors"> <img src="https://contrib.rocks/image?repo=mudler/LocalAI" alt="Contributors" /> </a>LocalAI alternatives
View more →Similar mcp servers in Design & Media, ranked by GitHub stars. Compare licence, recent activity and scan status before you choose.
| Name | Stars | Licence | Last updated | Scan |
|---|---|---|---|---|
| LocalAI (this page) mudler | 50k | MIT | Nov 1, 2026 | Scanned, no flagged issues |
| Next AI Draw Io DayuanJiang | 37k | Apache-2.0 | Nov 1, 2026 | Scanned, no flagged issues |
| MCP For Blender ahujasid | 33k | MIT | Oct 29, 2026 | Scanned, no flagged issues |
| Figma Context MCP GLips | 16k | MIT | Oct 27, 2026 | Scanned, no flagged issues |
| Nginx UI 0xJacky | 12k | AGPL-3.0 | Nov 1, 2026 | Scanned, no flagged issues |
| Lamda firerpa | 8.7k | MIT | Sep 27, 2026 | Scanned, no flagged issues |