Matryca Plumber MCP Server
 by MarcoPorcellato
Local-first AI daemon for Logseq OG: background semantic indexing, link hygiene, and agent-ready CLI/MCP — edits Markdown on disk (no cloud, no Logseq API). Karpathy LLM-Wiki inspired.
Matryca Plumber is an open-source mcp server by MarcoPorcellato, written mainly in Python, with 101 GitHub stars and the Apache-2.0 license. Its code was last updated Nov 1, 2026. The latest PyPI release is matryca-plumber 2.0.0, published Aug 18, 2026, with 80 downloads last week.
Matryca Plumber





I gave an AI agent access to my notes. It corrupted them.<br> I built Matryca Plumber so that never happens again.
We are not building another "agentic memory"...
We are building the governed memory plane for humans and agents.
Human-owned memory. Agent-native access. Governed evolution.
Matryca Plumber does not define or require a graph database, vector database, embedding model or retrieval algorithm.
v2.0.0 is stable and available now. Matryca Plumber's default-on external Shadow DB, Strict Read Only protection, Markdown authority, and fail-closed fallback contract are now published on GitHub Releases and PyPI. Read the release record and changelog for the exact scope and upgrade notes.
Published maintenance prerelease:
v2.0.1-rc.1remains available for opt-in evaluation as an exact historical artifact. It adds a bounded, canonicaljournal_dayhandler that reads Markdown directly without querying Shadow or mutating a graph, alongside provider-free evidence tooling. Stablev2.0.0remains the default recommendation. The current development branch has advanced beyond that prerelease, so any later candidate or stable release requires its own exact-source qualification. See the release record and historical qualification plan.
RC2 terminal history; RC3 published; RC4 superseded:
v2.0.1-rc.2failed before GitHub Release creation and PyPI publication; its signed tag and workflow evidence are immutable but are not a public artifact, Gate B result, or stable-promotion credit.v2.0.1-rc.3is a published historical prerelease.v2.0.1-rc.4/2.0.1rc4remains unpublished. An earlier exact candidate (74884c38) has source, build, and installed-resource evidence, but later changes require their own exact-source qualification. No RC4 tag, public artifact, Gate B result, or stable promotion exists. See the RC2 failed-publication record, RC3 publication record, and historical RC4 preparation and qualification plan.
Experimental
2.1.0a4release track — pre-publication checkpoint, 2026-11-15. The active qualification plan covers bounded, cancellable dashboard reads and explanatory read-only bootstrap status. On Linux/macOS, dashboard work has a request-owned process group, an 1800-second execution budget and one five-second cleanup deadline; this is containment, not a performance fix, and legacy Windows behavior remains unchanged. The four additive bootstrap fields describe graph-local catalog progress, not external Shadow readiness. The published alpha.3 OG producer handoff and its synthetic Trama acceptance remain historical and unchanged; alpha.4 establishes no new real-vault or consumer admission, database support, stable support, or network-isolation claim. The qualification plan records pre-tag installed-runtime evidence for source commit6b86b02b17d37abcc68eec4af546c483280b7f3e; that evidence does not qualify later documentation changes or future public bytes. At this checkpoint no alpha.4 tag or public artifact existed; consult the release page for subsequent publication status.v2.0.0remains the default recommendation. The supersession record preserves RC4 history and its unfinished full-qualification obligations. The alpha.3 public producer handoff remains historical evidence only.
Local-first human/agentic memory inspired from Logseq OG and maintenance for Logseq. Matryca Plumber gives humans and agents one safe, structured interface to a Markdown knowledge graph—without turning an opaque database or a model provider into the owner of that knowledge.
Video Overview: Watch this to learn how Matryca Plumber works, how it connects to the wider Matryca ecosystem, and where it fits in shared human/agentic memory.
Quick start
Requires Python 3.12 or newer and a Logseq OG graph.
# Run the UI without installing anything permanently
uvx matryca-plumber status
Open http://127.0.0.1:8500, select a cloned Logseq graph, review the pre-flight checks, and start the engine when ready.
# Optional: install the command and its background service
uv tool install matryca-plumber
matryca service install
Start with a clone of your graph, especially before enabling writes or applying an import. See the operator contract, security policy, and support guide.
To install the stable release explicitly:
uv tool install matryca-plumber==2.0.0
Evaluators may still install the published RC1 historical artifact explicitly without changing the stable recommendation:
uv tool install matryca-plumber==2.0.1rc1
2.0.1rc2 was not publicly released and must not be installed. 2.0.1rc3 is a
published historical prerelease and may be installed only for evaluation:
uv tool install matryca-plumber==2.0.1rc3
2.0.1rc4 is not published and must not be installed. Alpha.4 is in release
preparation, not an installation recommendation or publication record; do not
install it unless and until public qualification and publication are recorded.
Existing synthetic Trama
alpha.3 acceptance does not qualify alpha.4. Neither RC3 availability nor alpha
preparation proves Gate B or stable qualification.
The ordinary quick start above is not the experimental OG gateway bootstrap.
That gateway requires a dedicated environment with the complete hash-locked
Parser 1.9.0 dependency profile, followed by installation of the verified public
wheel with --no-deps. The broad application dependency range and an ordinary
uvx resolution do not qualify this exact profile. Follow the
alpha plan
only after its public artifacts and profile pass the declared gates.
What v2.0.0 changes
The stable v2 release makes the Shadow read path a practical default while keeping ownership and mutation boundaries explicit:
- External Shadow DB by default: healthy FTS5 and subtree reads use a disposable
cache outside the Logseq graph; set
MATRYCA_SHADOW_DB_ENABLED=falseto opt out. - Strict Read Only remains useful:
MATRYCA_READ_ONLY=trueblocks graph-local mutation while validated external Shadow maintenance remains available. - Markdown remains authoritative: Shadow never replaces Logseq Markdown, OCC, or the parser-aware write plane. Unavailable, stale, or unhealthy Shadow state falls back to Markdown-backed BM25 reads.
- Qualified parser baseline and supported range: v2.0.0 was qualified with
logseq-matryca-parser1.7.1; package metadata accepts>=1.7.1,<2.0.0, so a fresh install can resolve a newer parser within that declared range. The experimental 2.1.0 track qualifies only its declared exact Parser profile; a metadata range is not gateway qualification for other resolved versions.
Biological memory, native Logseq DB Safe-Sync writes, content-aware Tana merge, and proactive adaptive runtime remain future work; they are not silently included in the v2.0.0 contract.
Experimental 2.1.0 alpha scope
The proposed 2.1.0a4 candidate retains the existing content-free OG identity
and topology profile while adding bounded dashboard execution and read-only
bootstrap explanations. The only changed read targets are dashboard and
bootstrap_status, available through the corresponding explicit CLI and MCP
selectors. Dashboard execution is bounded and cancellable on Linux/macOS; it is
not a performance claim, and Windows keeps the legacy route. Bootstrap metadata
does not change catalog truth, write policy or Shadow status. The new resource
generator refreshes only version/root-lock-derived link digests; schemas, fixtures,
topology golden and packaged Parser requirements remain unchanged. The published
alpha.3 producer handoff is not transferred to alpha.4.
The existing synthetic Trama alpha.3 acceptance is not extended or revised by this candidate. Alpha.4 does not establish real-vault compatibility, new Trama admission, Logseq database support, stable support or network isolation. The alpha.4 qualification plan keeps its preparation, pre-tag runs, tag, public-byte verification and final inventory as separate gates.
<a id="what-the-proposed-v201-rc4-candidate-adds"></a>
Historical v2.0.1 RC4 candidate scope
This section preserves the superseded, unpublished RC4 scope. It does not define the current alpha scope or claim that no historical RC4 candidate was selected.
journal_day is a narrow read target for one canonical ISO-dated Logseq journal. It
keeps the same ownership model as v2: Markdown is authoritative, the response carries
bounded provenance and a source digest, malformed dates and pagination requests fail
closed, and the handler neither initializes nor queries a Shadow cache. Ordinary CLI
or MCP process startup may still prepare the configured Shadow profile before dispatch;
that separate bootstrap is unchanged. The feature is useful when an operator or agent
needs one day of context without widening retrieval to the surrounding graph.
The proposed candidate does not change the default-on Shadow contract, Read Only boundaries, or write plane. It adds an internal, session-bound OG topology projection and packages only static public contract/TCK bytes; it does not expose a Python adapter, transport, CLI/MCP route, Logseq DB feature, consumer wiring, UI, or LENS surface. Its evidence tooling remains provider-free and is not a benchmark, a real-agent evaluation, or a release result. RC4 preparation has no tag, public artifact, Gate B result, or stable-promotion decision. RC2 and RC3 historical evidence cannot qualify RC4.
Why Matryca Plumber
Most agent memory systems ask you to trust an internal store. Matryca Plumber starts from the opposite premise: your human-readable Logseq Markdown remains the system of record.
| Principle | What it means in practice |
|---|---|
| Human-owned memory | Pages and blocks stay readable, editable, portable Markdown. |
| Safe agent access | CLI and MCP expose structured graph operations instead of ad hoc file edits. |
| Conflict-aware writes | Optimistic concurrency control and page locks reject stale updates rather than silently overwrite human work. |
| Fast, disposable reads | The Shadow DB accelerates search and subtree reads, but can be rebuilt and never becomes authoritative. |
| Useful Read Only mode | Agents can benefit from an external Shadow cache while graph-local mutation remains blocked. |
| Local-first operation | The graph stays on disk; local inference works without a cloud API key. |
This makes Matryca Plumber more than a vector store or chat-history database. It is a controlled memory plane where humans keep custody of knowledge and agents receive the structure, speed, and safety they need to work with it.
A different model of agentic memory
Mem0 and many other service-centric memory layers solve an important problem: they extract, store, and retrieve scoped memories so an application can personalize an agent across sessions. Matryca Plumber solves a different problem: how humans and agents can safely maintain the same durable body of knowledge.
| Question | Service-centric memory, such as Mem0 | Matryca Plumber |
|---|---|---|
| What is the primary memory object? | An extracted fact, event, or memory record | A human-readable Logseq page or addressable block |
| Where does truth live? | In the memory layer's configured stores | In the user's Markdown graph |
| How does a human participate? | Primarily through the application, API, or management surface | Directly in the same pages and blocks used by agents |
| How is context retrieved? | Memory search and ranking over the service's stores | Structured graph reads, BM25, and an optional derived Shadow DB |
| How is knowledge changed? | Memory extraction and add/update/delete operations | Parser-aware block mutation guarded by OCC and write policy |
| What is the design goal? | Persistent, scoped recall for an application or agent | A shared cognitive workspace owned by the human |
Why block granularity matters
Logseq's outliner gives Matryca Plumber a natural unit of memory that is both
machine-addressable and human-readable. A block can have a durable id:: UUID,
properties, children, links, and a precise place in the graph.
When an agent already knows that anchor, Matryca can:
- retrieve only the block and its descendants instead of placing the entire page in the model's context;
- narrow the result again to one heading, or bound a Shadow query by depth, node count, and output bytes;
- append beneath a specific parent or edit only the permitted property lines inside that block's span;
- preserve the surrounding page and reject a stale write through dry-run, page locks, and OCC.
This reduces prompt tokens and irrelevant context, makes retrieval more focused, and shrinks the area in which an agent can make a mistaken edit. A Markdown fallback may still read the page locally to locate the block, and an atomic commit persists the page file, but the model does not need to ingest or regenerate the whole document.
Page-centric Markdown integrations often lack this boundary and must provide a much larger document to the model for a small read or update. Not every agent-memory system is page-centric—Mem0 also stores granular extracted memories. Matryca's distinction is that its granular unit remains the same canonical block the human reads and edits, not a separate derived memory record. See the targeted subtree contract for the exact read surface.
The decisive distinction is not merely local versus cloud, or Markdown versus a database. It is which representation remains authoritative. Matryca Plumber uses a database where it is valuable—for fast derived reads—without moving ownership away from the documents a human can inspect, edit, link, version, and keep independently of any agent.
This is an architectural comparison, not a claim that one category replaces every other. Mem0 supports both hosted and self-hosted deployments and is optimized for a different integration boundary. For the longer argument and the design philosophy behind Matryca Plumber, read The Agentic Memory Dilemma: Mem0 vs. Matryca Plumber and the Future of Human-AI Collaboration.
What it provides
- Agent-native CLI and MCP for pages, blocks, search, context, ingestion, and guarded mutation.
- Derived Shadow DB with SQLite FTS5 and subtree reads, external cache isolation, health checks, fallback, and quarantine behavior.
- Background maintenance for semantic indexing, link hygiene, entity consolidation, and other explicitly enabled operations.
- Logseq-aware writes through the parser and one shared OCC-protected mutation plane.
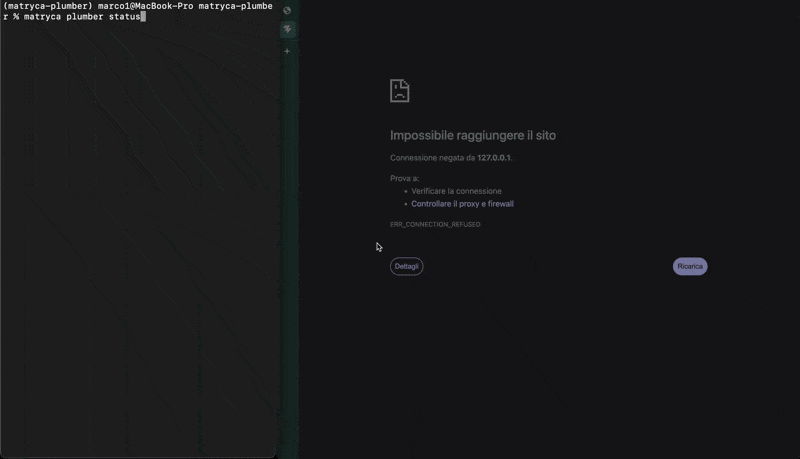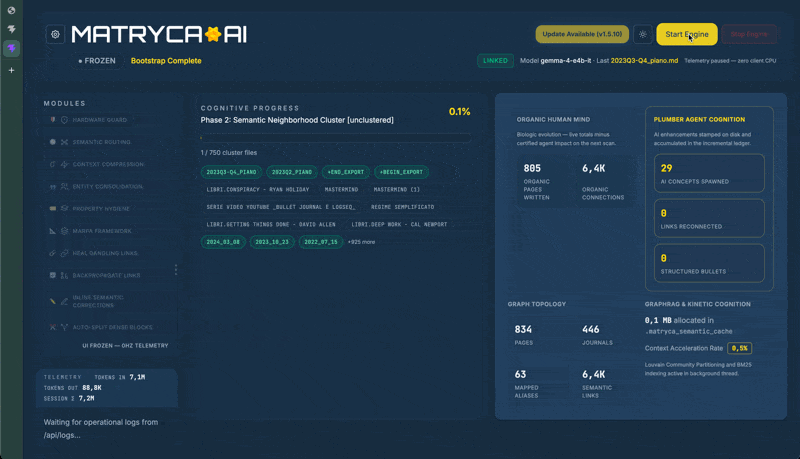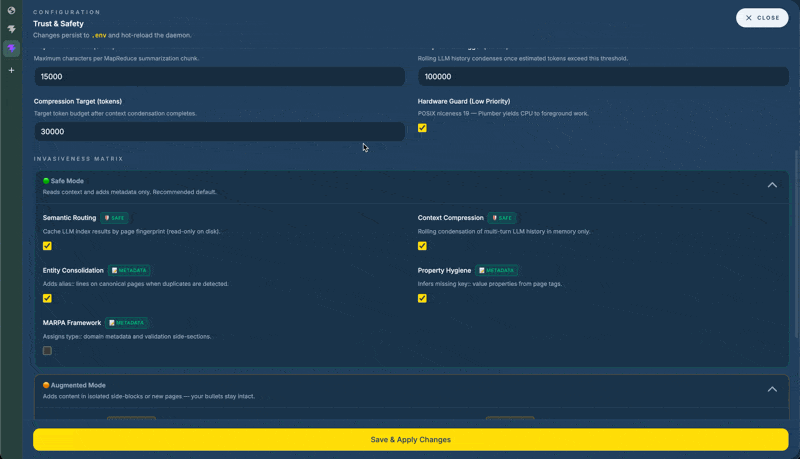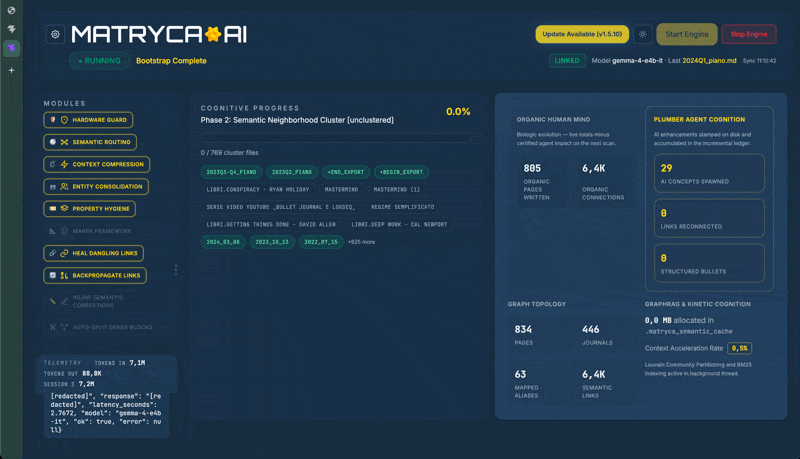
- Sovereign UI for setup, trust controls, health, and runtime telemetry.
- Tana to Logseq OG migration, streamed and dry-run by default.
For the complete and current behavior, use the documentation paths rather than this overview.
Choose how much gardening you want
Matryca separates the permission to write from the kind of maintenance it may perform. Strict Read Only is the hard boundary: while it is enabled, every graph-writing control is unavailable. Reads still work, and Shadow DB Acceleration may independently maintain its disposable cache outside the Logseq graph.
When writes are allowed, the traffic-light levels let you choose how actively Matryca Plumber tends the graph:
| Level | Features you can activate | What may change |
|---|---|---|
| 🟢 Safe Mode | Semantic Routing; Context Compression; Entity Consolidation; Property Hygiene; MARPA Framework | Routing caches and compressed context do not touch the graph. The other controls may add alias::, inferred properties, classification metadata, or validation side-sections—never rewrite original bullet prose. |
| 🟡 Augmented Mode | Heal Dangling Links; Backpropagate Links | Adds isolated seed pages or backlink-context sections while preserving original bullets. |
| 🔴 Surgeon Mode | Inline Semantic Corrections; Auto-Split Dense Blocks | May edit original bullet text or restructure dense subtrees. Enable explicitly and test on a cloned graph first. |
This means Matryca can remain a fast, read-only memory layer, or become an opt-in knowledge gardener that consolidates entities, improves properties, repairs missing link targets, and strengthens connections between notes. Start with Strict Read Only, then enable only the smallest gardening level that matches your needs.
See the architecture trust levels and Shadow DB operator contract for the exact boundaries.
How it works
flowchart LR
  Human["Human in Logseq"] <--> Markdown[("Logseq Markdown\nsystem of record")]
  Agents["Agents"] --> Access["CLI + MCP"]
  UI["Sovereign UI"] --> Runtime["Maintenance runtime"]
  Access --> ReadPlane["Structured read plane"]
  Access --> WritePlane["OCC-protected write plane"]
  Runtime --> ReadPlane
  Runtime --> WritePlane
  ReadPlane --> Shadow[("External Shadow DB\ndisposable cache")]
  ReadPlane --> Markdown
  WritePlane --> Parser["Logseq-aware parser"]
  Parser --> Markdown
  Markdown -. "rebuild / reconcile" .-> Shadow
The read and write paths have deliberately different authority:
- Reads may use the Shadow DB when it is enabled, healthy, and fresh; otherwise they fall back to Markdown-backed indexes.
- Writes always pass through the shared mutation plane and parser. Shadow maintenance cannot roll back an authoritative Markdown write.
- Strict Read Only blocks graph-local mutation while permitting validated external derived-cache writes.
Current defaults and exact fallback semantics live in the canonical Shadow DB operator contract.
Common workflows
Give an agent structured graph access
uvx --from matryca-plumber matryca --json read page "My Project"
uvx --from matryca-plumber matryca context load "My Project"
Agent hosts should start with llms.txt. MCP is disabled until explicitly
trusted and enabled by the operator.
Import a Tana workspace
export LOGSEQ_GRAPH_PATH=/path/to/a/cloned/logseq/graph

# Inspect first; no graph writes by default
matryca import tana --file ~/Downloads/workspace.json

# Apply only after reviewing the dry-run report
matryca import tana --file ~/Downloads/workspace.json --apply
See the Tana import contract for mapping, idempotency, and large-export behavior.
Run the local services
| Command | Result |
|---|---|
matryca plumber status | Open the UI and local API; the daemon remains under operator control. |
matryca plumber start | Start the background maintenance daemon. |
matryca plumber stop | Stop the daemon. |
Documentation
| If you want to… | Start here |
|---|---|
| Install, configure, and operate v2 | Shadow DB runtime and operator contract |
| Understand the system | Architecture |
| Integrate an agent | llms.txt and agent onboarding |
| Review features and contracts | OpenSpec index |
| Contribute | First contribution and contributor guide |
| Follow releases | Changelog and release process |
| Review the stable v2.0.0 outcome | Release record and readiness decision |
| Review v2.0.1-rc.1 evidence | Historical prerelease record and artifact-bound qualification plan |
| Track proposed experimental 2.1.0a4 preparation | Active alpha.4 qualification plan and RC4 supersession record |
| Review the superseded v2.0.1-rc.4 path | Historical RC4 release preparation and qualification plan |
| Navigate the documentation system | Knowledge index |
| Review the 34-PR excellence milestone | Repository excellence milestone |
| Follow the current repository reconciliation | GitHub and repository reconciliation |
Project and community
- Issues — bugs and trackable feature work
- Discussions — design proposals and questions
- Contributing — development setup and quality gates
- Code of Conduct — community expectations
- Security — private vulnerability reporting
- Sponsor — support continued work
Matryca Plumber is developed by Marco Porcellato and Matryca.ai. Product naming and identity are defined in the branding guide.
License
Apache-2.0 — see LICENSE.
Matryca Plumber alternatives
View more →Similar mcp servers in Developer Tools, ranked by GitHub stars. Compare licence, recent activity and scan status before you choose.
| Name | Stars | Licence | Last updated | Scan |
|---|---|---|---|---|
| Matryca Plumber (this page) MarcoPorcellato | 101 | Apache-2.0 | Nov 1, 2026 | Scanned, no flagged issues |
| MCP Use mcp-use | 11k | MIT | Oct 30, 2026 | Scanned, no flagged issues |
| MobileBuildMCP getsentry | 6.5k | MIT | Nov 1, 2026 | Scanned, no flagged issues |
| Gemini Notebook MCP CLI jacob-bd | 6.4k | MIT | Oct 27, 2026 | Scanned, no flagged issues |
| Mcporter openclaw | 5.1k | MIT | Oct 27, 2026 | Scanned, no flagged issues |
| Flint Chart microsoft | 4.5k | MIT | Nov 1, 2026 | Scanned, no flagged issues |